Benchmark · OSWorld 2.1
Sai on OSWorld 2.1
OSWorld measures computer-use agents on 108 long-horizon tasks in real desktop apps. On the official OSWorld 2.1 leaderboard, Sai with Claude Opus 5 has the highest partial score, and it is the only OSWorld 2.1 entry that publishes what a task costs.
- Partial score, the highest on the leaderboard
- 79.38%
- Binary accuracy, second on the leaderboard
- 41.67%
- Per task, the only published cost on OSWorld 2.1
- $14.34
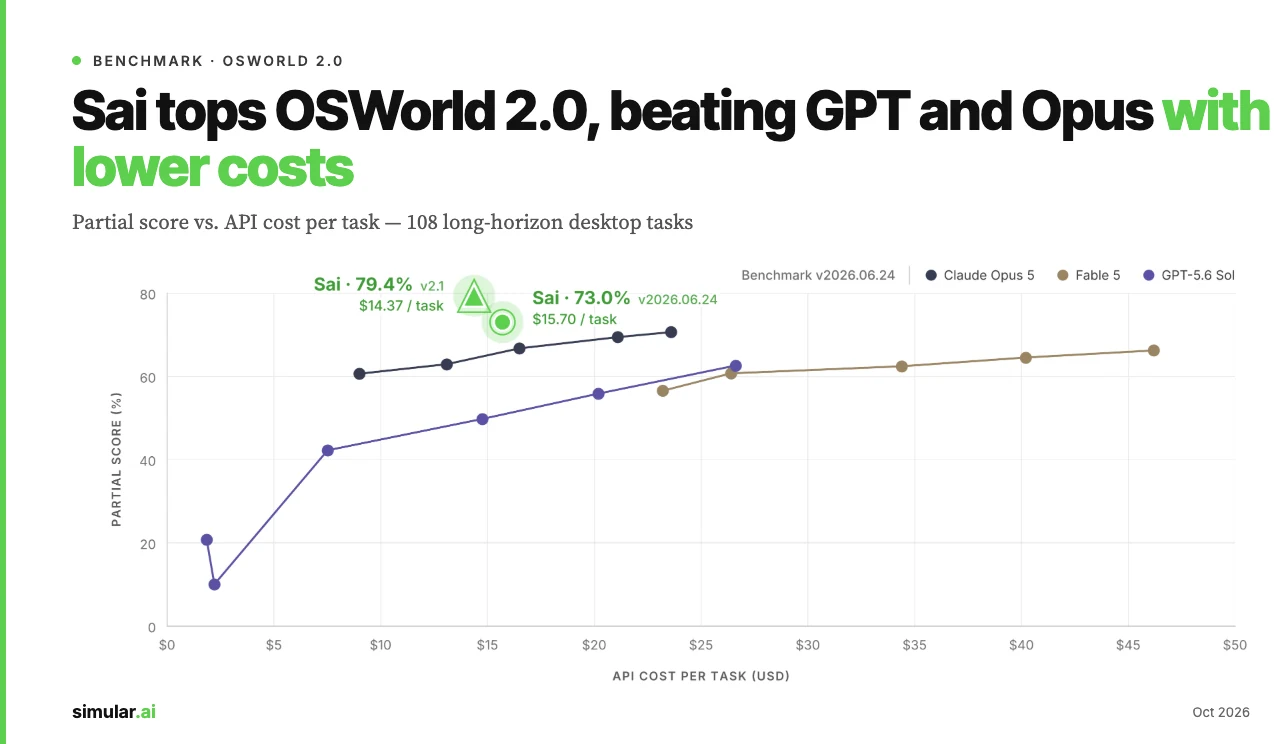
Leaderboard
From the official OSWorld leaderboard by XLANG Lab. Check the full resource → osworld-v2.xlang.ai
| Rank | Model | Approach | Trajectories | Reproduce | |||
|---|---|---|---|---|---|---|---|
| 1 | Claude Opus 5Anthropic | MaxBatch toolv2.1 | 44.33% | 77.67% | — | — | — |
| 2 | Sai w/ Claude Opus 5SimularAgent | Maxv2.1 | 41.67% | 79.38% | $14.34 | Hugging Face | PlatformQuick start |
| 3 | Claude Opus 5Anthropic | HighBatch toolv2.1 | 36.89% | 68.92% | — | — | — |
| 4 | Claude Opus 5Anthropic | XhighBatch toolv2.1 | 33.33% | 73.11% | — | — | — |
| 5 | Claude Opus 5Anthropic | MediumBatch toolv2.1 | 33.01% | 64.85% | — | — | — |
| 6 | Claude Opus 5Anthropic | MaxBatch toolv2026.08.08 | 31.43% | 68.31% | — | — | — |
| 7 | Claude Opus 5Anthropic | XhighBatch toolv2026.08.08 | 30.21% | 67.67% | — | — | — |
| 8 | Claude Opus 5Anthropic | HighBatch toolv2026.08.08 | 28.98% | 63.79% | — | — | — |
| 9 | GPT-5.6 SolOpenAI | MaxBatch toolv2026.08.08 | 27.34% | 62.72% | — | — | — |
| 10 | Claude Opus 5Anthropic | MediumBatch toolv2026.08.08 | 25.33% | 60.49% | — | — | — |
| 11 | Claude Opus 5Anthropic | LowBatch toolv2026.08.08 | 22.32% | 54.89% | — | — | — |
| 12 | Claude Opus 4.8Anthropic | MaxBatched toolv2026.06.24 | 20.6% | 54.8% | — | — | — |
| 13 | Claude Opus 5Anthropic | LowBatch toolv2.1 | 18.81% | 59.09% | — | — | — |
| 14 | Claude Opus 4.8Anthropic | MaxStandardv2026.06.24 | 18.52% | 49.33% | — | — | — |
| 15 | Claude Opus 4.7Anthropic | MaxBatched toolv2026.06.24 | 18.2% | 48.91% | — | — | — |
| 16 | Claude Opus 4.7Anthropic | MaxStandardv2026.06.24 | 13.9% | 49.1% | $35.8 | — | — |
| 17 | GPT-5.5OpenAI | XhighBatch toolv2026.06.24 | 13.0% | 49.5% | $25.5 | — | — |
| 18 | Claude Sonnet 4.6Anthropic | MediumStandardv2026.06.24 | 9.3% | 33.9% | $14.4 | — | — |
| 19 | Claude Sonnet 4.6Anthropic | MaxStandardv2026.06.24 | 8.3% | 41.5% | $22.3 | — | — |
| 20 | MiniMax M3MiniMax | EnabledStandardv2026.06.24 | 4.6% | 22.3% | $2.4 | — | — |
| 21 | Kimi 2.6Moonshot AI | EnabledStandardv2026.06.24 | 4.6% | 22.1% | $6.6 | — | — |
| 22 | Qwen 3.7-PlusAlibaba | ThinkingStandardv2026.06.24 | 2.8% | 21.5% | $3.8 | — | — |
¹ Offline set: 82 tasks that run without internet access. v2026.08.08 results average 7 runs for Claude Opus 5 and 2 runs for GPT-5.6 Sol. Rows without a release are the v2026.06.24 release.
Last updated by the benchmark authors on 2026-10-05.
Run the agent behind the score
The same Sai is one API call away. Get a key in a minute, or talk to us about running it at scale.